Prompt engineering is the systematic process of designing natural language requests to elicit accurate, high-quality responses from large language models. While modern AI models are capable of sophisticated reasoning, their outputs are heavily dependent on the clarity, context, and constraints provided within the initial prompt. Ensuring accuracy is not a one-time task but an iterative cycle of refinement, where users must observe model behavior and adjust instructions to minimize ambiguity and hallucinations. By treating prompt design as an engineering discipline, practitioners can move beyond unpredictable results and establish a reliable framework for content generation.
To achieve reliable results, practitioners must move beyond simple questions and adopt structured strategies such as few-shot prompting, schema enforcement, and negative constraints. This guide provides a comprehensive checklist for reviewing AI-generated content, focusing on the technical frameworks used by developers to optimize model performance. By understanding how models interpret different input types and how to implement rigorous evaluation cycles, you can significantly improve the factual integrity and utility of AI outputs. This systematic approach ensures that the model remains grounded in the provided data and adheres to the specific requirements of the task at hand.
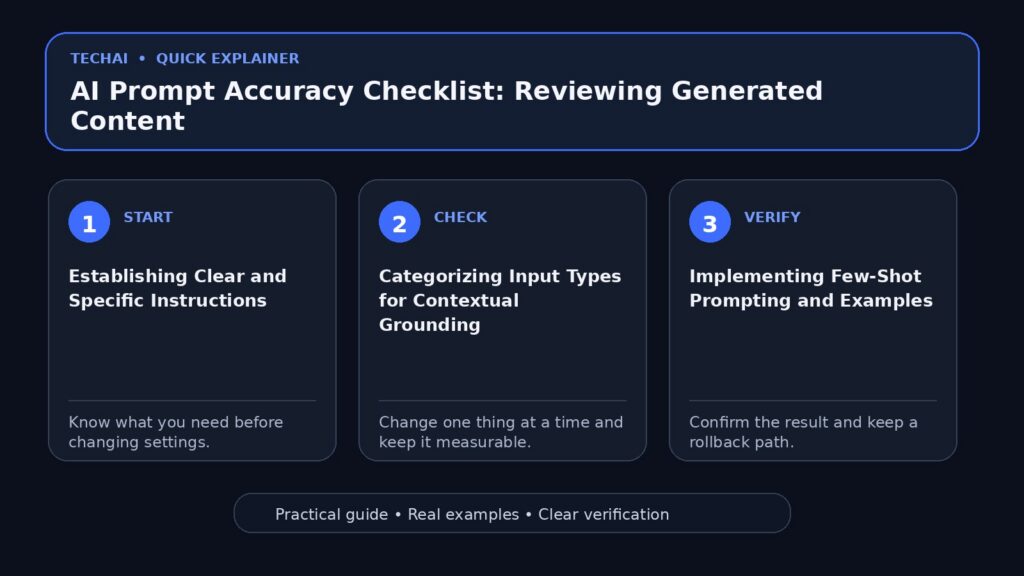
Establishing Clear and Specific Instructions
The most effective way to customize model behavior is to provide clear and specific instructions. Vague prompts often lead to generalized or irrelevant responses because the model is forced to make assumptions about the user's intent. Instructions should be treated as a set of requirements, ranging from simple questions to complex, multi-step tasks that map out a specific user experience or mindset. When instructions are ambiguous, the model may default to its pre-trained biases rather than the specific context you intend to provide.
When drafting instructions, it is helpful to define the persona the model should adopt and the specific goal it needs to achieve. For instance, instead of asking for a 'summary,' a more accurate prompt would specify the target audience, the desired tone, and the key points that must be included. This reduces the model's interpretation overhead and aligns the output with the intended use case. Using explicit verbs like 'classify,' 'summarize,' or 'extract' helps the model understand the exact operation it needs to perform on the input data.
Furthermore, breaking down complex requests into sequential, step-by-step tasks can significantly improve accuracy. If a task requires multiple logical leaps, providing a roadmap within the prompt allows the model to process each stage individually. This method, often referred to as chain-of-thought prompting, ensures that the model does not skip critical reasoning steps that lead to the final answer. By being explicit about the process, you minimize the risk of the model reaching a correct-looking but logically flawed conclusion.
- Define the specific role or persona the AI should assume.
- Break down complex requests into sequential, step-by-step tasks.
- Specify the target audience to calibrate the technical depth.
- Use explicit verbs to define the action (e.g., 'classify', 'extract').
Categorizing Input Types for Contextual Grounding
Accuracy is often determined by how well the model understands the relationship between the instruction and the provided data. Official documentation identifies four primary input types: Question, Task, Entity, and Partial input. Recognizing which type you are using allows you to structure the prompt to highlight the most relevant information for the model's reasoning process. For example, a Question input seeks a direct answer, whereas a Task input requires the model to perform a specific operation, such as generating a list or transforming data into a new format.
Entity inputs involve the model operating on specific objects, such as classifying a list of items like 'Elephant' or 'Snail' into categories like 'Large' or 'Small.' Partial inputs, on the other hand, leverage the model's auto-completion capabilities to continue a thought or code block. By providing a prefix, you guide the model's completion logic toward a specific style or structure. Mixing these types without clear separation can confuse the model and lead to factual errors, as the model may struggle to distinguish between the data it should process and the instructions it should follow.
To maintain high accuracy, it is essential to clearly delineate where the instructions end and the input data begins. Using delimiters or specific headers for each input type helps the model parse the prompt more effectively. When the model understands the role of each text segment, it can apply its reasoning capabilities more precisely to the target entity or task. This structural clarity is a fundamental requirement for any prompt intended for production-level accuracy.
- Question Input: Direct queries requiring factual or creative answers.
- Task Input: Specific operations the model must perform on data.
- Entity Input: Objects or data points the model must classify.
- Partial Input: Providing a prefix to guide the model's completion logic.
Implementing Few-Shot Prompting and Examples
Few-shot prompting involves providing the model with one or more examples of the desired input-output pair. This is one of the most powerful techniques for ensuring accuracy, as it demonstrates the expected format, tone, and logic without relying solely on descriptive text. Examples act as a template that the model can mirror, which is particularly useful for complex formatting or niche tasks where natural language descriptions might be insufficient. By seeing a successful execution of the task, the model can infer the underlying rules more accurately.
When using examples, it is critical to ensure they are representative of the actual task. If the examples are inconsistent or contain errors, the model will likely replicate those flaws in its generated content. For high-stakes accuracy, providing a 'chain of thought' example—where the reasoning process is shown alongside the answer—can help the model navigate logical hurdles more effectively. This allows the model to follow a proven path of reasoning, reducing the likelihood of hallucinations or logical gaps in its own output.
The number of examples provided can vary, but typically 1 to 5 high-quality examples are sufficient to steer the model. Providing too many examples can lead to 'prompt drift' or exceed the model's context window, while too few may not provide enough signal for complex tasks. The goal is to provide enough variety so the model understands the general rule rather than just memorizing the specific examples. This balance is key to creating a prompt that is both accurate and flexible across different inputs.
- Provide 1-3 high-quality examples of the desired output.
- Ensure examples follow the exact formatting required (e.g., JSON).
- Use examples to demonstrate how to handle edge cases.
- Include reasoning steps in examples to improve logical accuracy.
Applying Constraints and Negative Prompting
Constraints are essential for preventing the model from generating unwanted content or exceeding specific boundaries. You can tell the model both what to do and what not to do. Negative constraints, such as 'do not use technical jargon' or 'do not include information outside of the provided text,' are vital for maintaining factual grounding and preventing hallucinations. By explicitly forbidding certain behaviors, you narrow the model's search space, which often leads to more accurate and concise results.
Length constraints and formatting rules also fall under this category. By specifying that a response must be under a certain word count or must exclude specific topics, you force the model to prioritize the most relevant information. This is especially important when using models for data extraction, where extraneous commentary can interfere with automated processing. For instance, telling a model to 'return only the raw data with no introductory text' ensures that the output is immediately usable for downstream applications.
Another critical constraint is the source material limitation. If you want the model to act as a retrieval tool, you must instruct it to only use the provided context. This prevents the model from pulling in external, potentially outdated, or incorrect information from its training data. Setting these boundaries is a primary defense against the 'hallucination' phenomenon, where the model confidently asserts false information because it was not sufficiently constrained to a specific dataset.
- Set explicit word or character limits for the response.
- Use negative constraints to forbid specific topics or styles.
- Define the required format (e.g., 'return only the raw data').
- Specify source material to limit the model's knowledge retrieval.
Validating Accuracy with Structured Outputs
For applications where the generated content must be used by other software, structured outputs like JSON are preferred over natural language. Using a JSON Schema allows you to enforce a specific structure, ensuring that the model provides all required fields and adheres to data types. This significantly reduces the risk of the model omitting critical information or providing it in an unusable format. When the model is forced to fit its response into a predefined schema, it is less likely to wander off-topic or include irrelevant conversational filler.
Modern APIs allow for 'Structured Output' modes where the model is programmatically constrained to follow a specific schema. This is more reliable than simply asking the model to 'return JSON' in the prompt, as the model's internal sampling is guided by the schema requirements. When accuracy is paramount, using these programmatic constraints ensures that the output is not only factually correct but also syntactically valid for automated systems. This is particularly useful for tasks like order processing, where missing fields can cause system failures.
To optimize structured outputs, it is often helpful to provide a response prefix or a partial JSON block that the model can complete. This technique, combined with few-shot examples, provides the model with a clear starting point. By reducing the number of decisions the model has to make regarding the format, you allow it to focus more of its 'reasoning effort' on the actual content and accuracy of the data being populated into the fields.
- Use JSON Schema to define required fields and data types.
- Omit optional fields in the prompt to reduce output noise.
- Leverage API-level structured output settings for strict adherence.
- Verify that the model populates fields based on provided context.
The Iterative Optimization Cycle
Prompt engineering is rarely a 'one-and-done' task. It requires an optimization cycle that involves testing, evaluating, and refining. Developers often use 'Evals'—sets of test cases with known good answers—to measure how well a prompt performs across different scenarios. By running these evals, you can identify where the model consistently fails and adjust the prompt accordingly. This systematic approach is the only way to guarantee consistent accuracy over time, especially as models are updated or changed by providers.
This cycle may also include more advanced techniques like supervised fine-tuning or reinforcement learning from human feedback (RLHF). However, for most users, the cycle consists of observing model responses, identifying patterns of error, and adding clarifying instructions or examples to the prompt. If a model consistently misses a specific constraint, the prompt should be updated to emphasize that constraint or provide an example of how to handle that specific edge case. This feedback loop is essential for moving from a prototype to a production-ready prompt.
Monitoring for 'drift' is another critical part of the optimization cycle. As models evolve, a prompt that worked perfectly one month might produce different results the next. By maintaining a set of 'golden' test cases, you can quickly verify if a model update has impacted the accuracy of your generated content. This proactive approach ensures that your AI-driven workflows remain reliable and that any degradation in performance is caught before it affects the end-user experience.
- Create a set of 'golden' test cases to evaluate prompt changes.
- Use graders or automated scripts to check for specific keywords.
- Refine prompts based on observed failures in edge cases.
- Monitor for 'drift' where model updates change effectiveness.
Safety, Red Teaming, and Hallucination Mitigation
Accuracy also encompasses safety and the prevention of misinformation. Red teaming is the process of intentionally trying to provoke the model into generating incorrect, biased, or harmful content to identify weaknesses. By understanding where a model is prone to 'hallucinate'—or invent facts—you can build guardrails into your prompts to prevent these occurrences. This might involve setting safety classifiers or using specific model parameters that prioritize reasoning over creative generation.
Using reasoning models that show their 'thought process' or 'reasoning signatures' can also help in identifying where a logical error occurred during generation. When you can audit the model's internal logic, you can pinpoint exactly which part of the prompt led to an inaccurate conclusion. This transparency is vital for high-stakes applications in fields like law, medicine, or engineering, where a single factual error can have significant consequences. Auditing the reasoning path allows for more precise prompt adjustments.
Finally, always cross-reference generated facts with official documentation or search tools. Even the most well-engineered prompt cannot guarantee 100% accuracy 100% of the time. Implementing a human-in-the-loop review process for critical content ensures that the final output meets the necessary standards of truth. By combining technical prompt engineering strategies with traditional fact-checking, you create a robust system for generating reliable AI content.
- Perform red teaming to find prompts causing factual breakdowns.
- Use safety settings to filter out high-risk or unverified content.
- Enable reasoning signatures to audit the model's internal logic.
- Cross-reference generated facts with official documentation.
Key takeaways
- Prompt engineering is an iterative process requiring constant testing and refinement.
- Few-shot prompting with 1-3 examples is significantly more effective than long descriptions.
- Structured outputs like JSON ensure data consistency and machine readability for automation.
- Negative constraints are essential for preventing hallucinations and irrelevant content.
- Evals and 'golden' test cases are required to measure and maintain prompt accuracy over time.
Common mistakes to avoid
- Using vague or overly broad instructions that leave too much to model interpretation.
- Failing to provide examples of the desired output format (relying on zero-shot prompting).
- Ignoring negative constraints, which leads to verbose, jargon-heavy, or irrelevant content.
- Assuming a prompt that works once will work perfectly for all edge cases without testing.
Useful TechAI links
FAQ
What is the difference between zero-shot and few-shot prompting?
Zero-shot prompting provides only the instruction without any examples, relying entirely on the model's pre-existing knowledge. Few-shot prompting includes one or more examples of the task, which helps the model understand the specific pattern, format, and tone required for the response.
How can I prevent the AI from making up facts or hallucinating?
To mitigate hallucinations, use negative constraints like 'only use the provided text' and provide a clear source for the model to reference. Additionally, asking the model to provide citations or to explain its reasoning step-by-step can help surface logical errors before they reach the final output.
Why should I use JSON instead of plain text for data-heavy tasks?
JSON provides a structured, predictable format that is easy for both humans and machines to verify. By using a JSON Schema, you can ensure the model includes all necessary data points and follows a specific hierarchy, which is much harder to enforce with natural language alone.
What are 'Evals' in the context of prompt engineering?
Evals are evaluation datasets used to measure the performance of a prompt across various scenarios. They consist of diverse inputs and their corresponding 'ideal' outputs, allowing you to run the prompt through many tests to see how often it produces the correct result.